PADD: Path-Aligned Decompression Distillation for Non-Router Teacher to Guide MoE Student Learning
Authors: Xinyue Peng, Yi Qian, Jiaojiao Lin, Wenjian Shao, Yanming Liu
The authors propose the Path-Aligned Decompression Distillation (PADD) framework, aiming to distill knowledge from dense teacher models without explicit routing to Mixture of Experts (MoE) student models. The method initializes expert functionality through teacher neuron clustering and combines online adaptive distillation with path refinement strategy optimization to achieve efficient knowledge transfer and routing learning under a fixed computational budget.
Paper Summary
Problem
Expanding large model capacity under a fixed computational budget faces challenges; dense models encounter inference bottlenecks, while training MoE from scratch is costly. Distilling from dense teachers to MoE students faces difficulties such as router cold start, path fragmentation, and capacity gaps, leading to hard-to-learn routing strategies and expert homogeneity.
Method Overview
- Backbone: Dense Teacher to MoE Student
- Key module: Teacher Neuron Clustering, Online Adaptive Distillation, PR-GRPO, Reward-Augmented Load Balancing
- Loss: Distillation Loss + Policy Optimization Loss + Load Balancing Loss
Takeaways
Personal understanding — corrections welcome
Experiments show that PADD enables MoE students to match or outperform dense teachers at the same inference cost. Teacher neuron clustering effectively addresses expert homogeneity, and PR-GRPO significantly improves routing training stability.
Limitations & Questions
Experiments focus primarily on mathematical reasoning benchmarks, and generalization to other task domains needs verification. The neuron clustering process may increase computational overhead during the initialization phase.
Reading Notes
Personal reading notes. Original paper: arXiv:2606.10369v1.
PADD: A Deep Dive into Path-Aligned Decompression Distillation Guiding MoE Student Learning
Paper Basic Information
- Paper Title: PADD: Path-Aligned Decompression Distillation for Non-Router Teacher to Guide MoE Student Learning
- Paper ID: 2606.10369v1
- Authors: Xinyue Peng, Yi Qian, Jiaojiao Lin, Wenjian Shao, Yanming Liu
- Affiliation: Intel Corporation, Zhejiang University
- Conference/Journal: ICML 2026 (Proceedings of the 43rd International Conference on Machine Learning)
Research Background and Motivation
With the continuous expansion of Large Language Models (LLMs), scaling model capacity under a fixed computational budget has become increasingly difficult. Dense Models face bottlenecks in training throughput, inference latency, and memory bandwidth when scaling to hundreds of billions or trillions of parameters. The Mixture-of-Experts (MoE) architecture decouples capacity from inference FLOPs by decoupling parameters into sparsely activated expert sub-networks, theoretically allowing the “decompression” of entangled dense representations into structured expert modules.
However, the authors point out the following challenges currently exist:
- High Training Cost: Most high-performance models are still dense, and training MoE from scratch is expensive.
- Structural Mismatch: Existing MoE-to-MoE distillation lacks generality because expert decomposition and routing strategies are incompatible.
- Difficulty in Dense-to-MoE: Dense teacher models lack an explicit Router. If directly performing Sparse Upcycling, the new router lacks supervision from dense teacher activations and must learn from scratch, leading to the “Router Cold Start” problem.
- Path Rupture and Gradient Instability: Traditional distillation only aligns outputs and cannot transfer internal processing preferences; discrete routing jumps can break the continuity of Chain-of-Thought, causing “Path Rupture” and destabilizing gradients.
- Expert Homogenization: Classic MoE load balancing only controls activation frequency, ignoring expert quality, leading to converging expert functions.
To address the above issues, the authors propose a framework named PADD (Path-Aligned Decompression Distillation), aimed at distilling knowledge from dense teacher models without routers into MoE student models while learning high-quality routing strategies.
PADD Framework Overview
The PADD framework proposed in the paper organizes knowledge distillation into two stages comprising four steps. The framework aims to recover learnable path structures from dense teachers and stabilize expert specialization under fixed inference costs.
As shown in Figure 1, the overall architecture of PADD is divided into:
- Initialization Stage (Stage I): Constructing functional diversity of student experts through teacher neuron clustering and student expert warmup.
- Training Stage (Stages II–IV): Integrating online adaptive distillation, path refinement strategy optimization, and reward-augmented load balancing within a single training pipeline.
Detailed Core Methods
Stage I: Expert Initialization and Warmup Alignment Based on Neuron Clustering
To address the router cold start and expert homogenization problems, PADD utilizes the activation patterns of neurons in the dense teacher FFN layer to initialize student experts during the initialization stage.
-
Activation Statistics and Clustering: The authors extract neuron weight vectors from the first linear layer () of the dense teacher FFN. Although dense models do not have explicit routing, their FFN neurons activate together under similar inputs, revealing an implicit modular structure. The authors perform cardinality-constrained K-Means clustering on teacher neurons, dividing them into clusters, with each cluster corresponding to an expert in the student model. Subsequently, the activation distribution of each cluster on the dataset is calculated as the target distribution for student expert learning. This step is statistical only and does not train the student model.
-
Expert Warmup: The student router weights are initialized using the centroids obtained from clustering. Subsequently, the student experts are warmed up using an independent dataset while freezing the router. This ensures that all experts receive balanced training signals in the early stages, forming initial functional differences aligned with the teacher’s implicit structure.
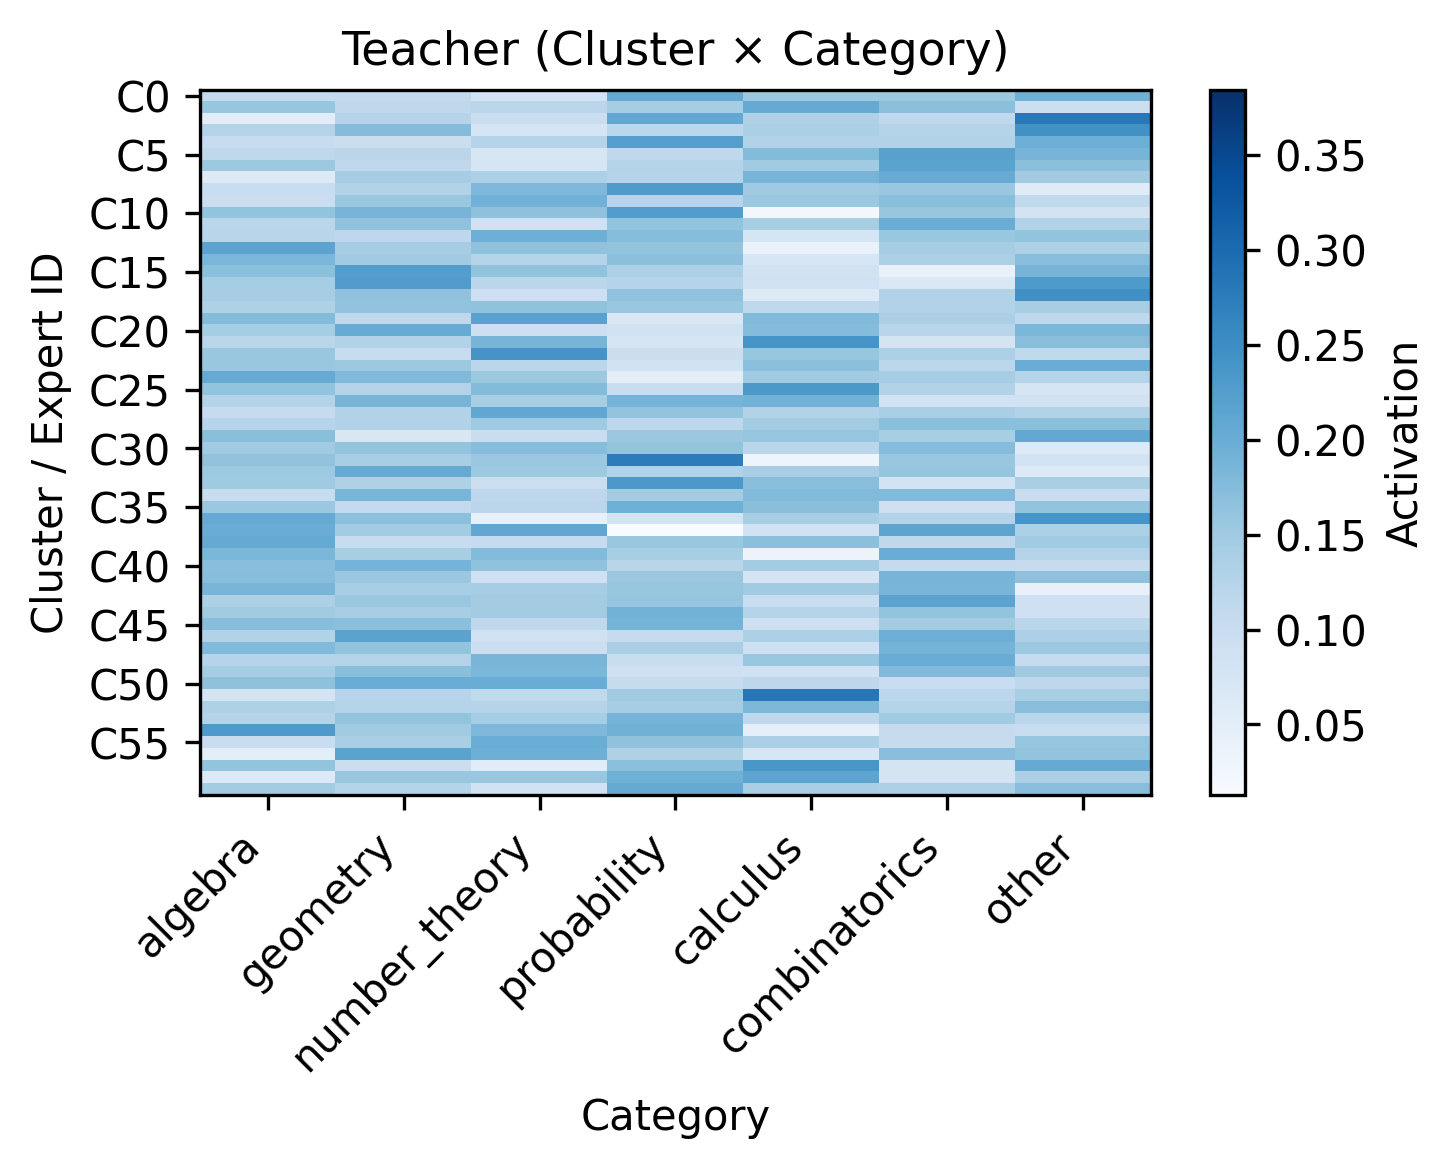
The paper visualizes the distillation effect of expert specialization structures. As shown in Figure 3, the authors display the distillation of expert specialization structures on the Qwen model. The heatmap reflects the correspondence between teacher model neuron activation intensity and MoE student expert activation, verifying that the initialization stage successfully captured the teacher’s implicit structure.
Stages II-IV: Online Adaptive Distillation and Strategy Optimization
After initialization is complete, the training stage begins, integrating various mechanisms to optimize routing and knowledge absorption.
-
Online Adaptive Distillation: Traditional offline distillation cannot guide MoE students in learning routing decisions. PADD proposes an online adaptive mechanism that provides smooth and absorbable semantic supervision along the student’s actual routing path. This helps bridge the capacity gap between dense teachers and MoE students, preventing fine-grained logits from being unabsorbable.
-
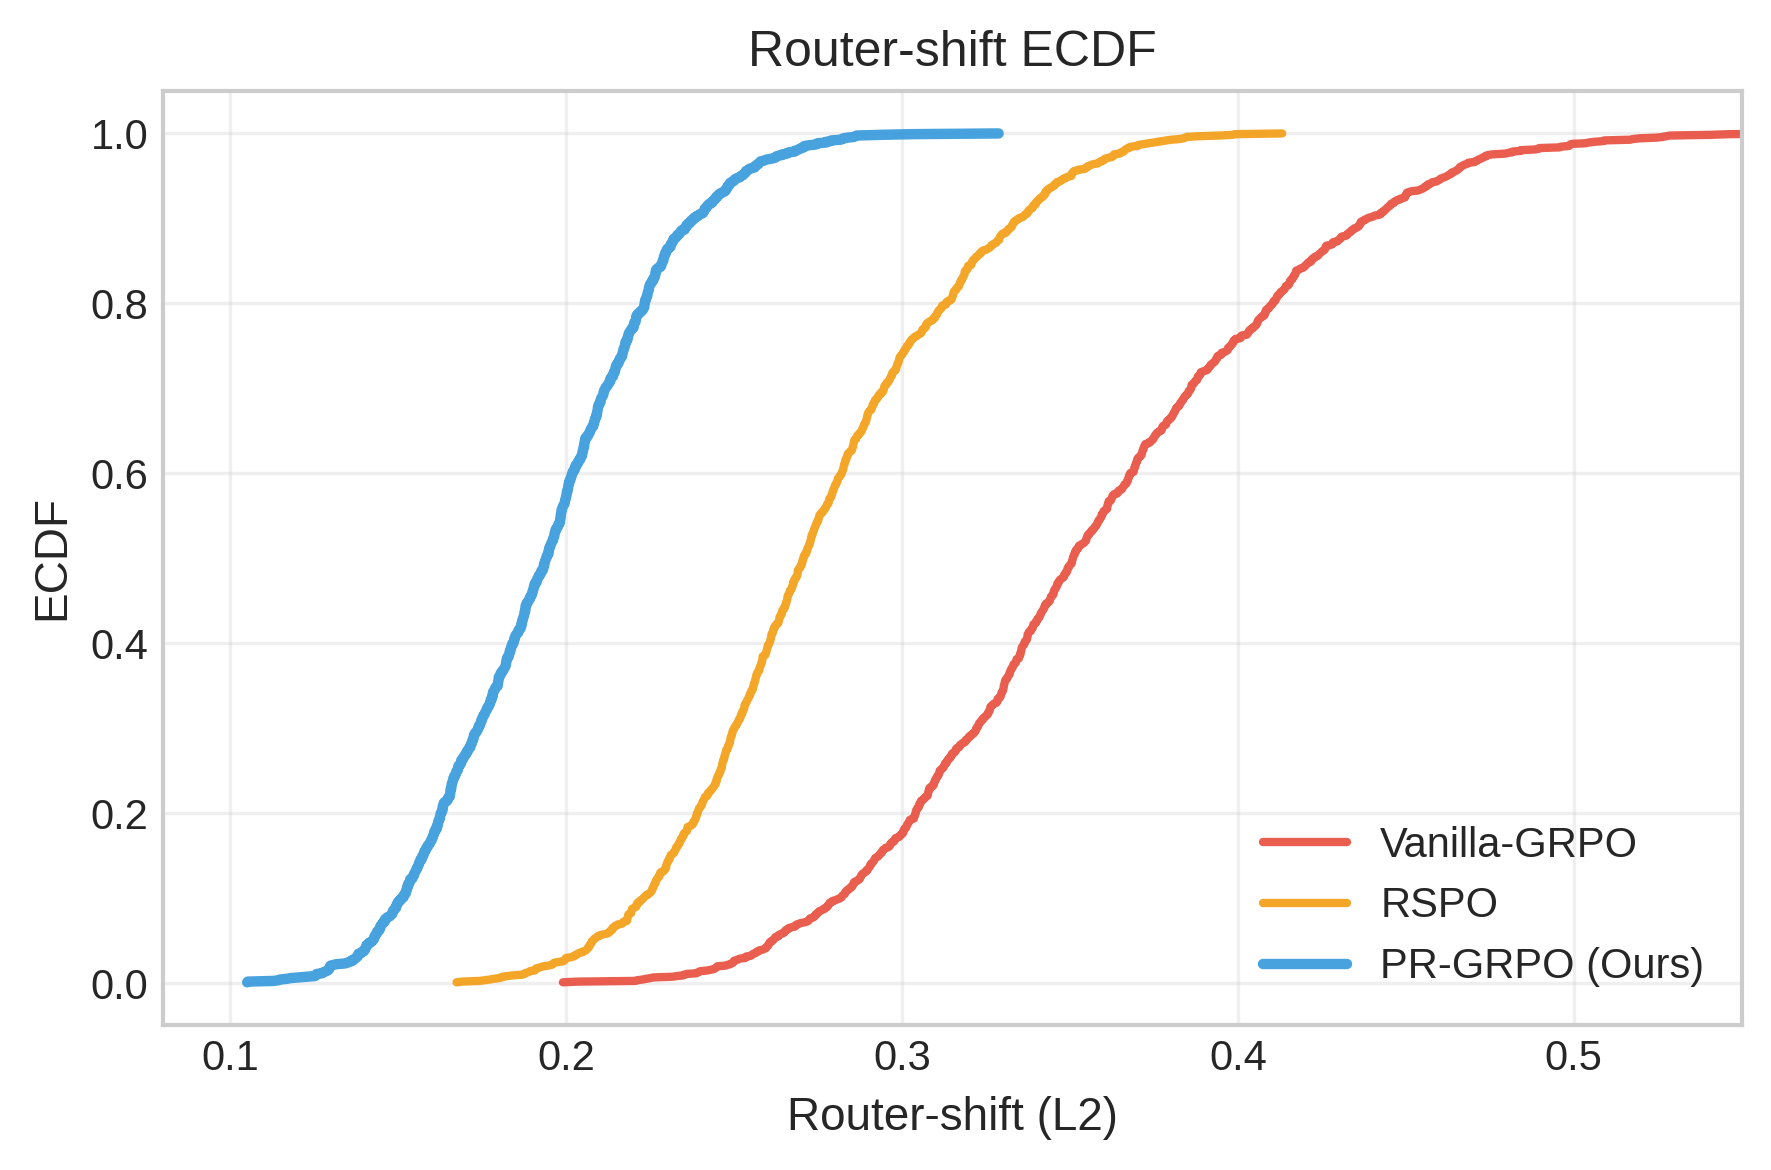
Path Refinement Group Relative Policy Optimization (PR-GRPO): To address gradient instability caused by discrete routing jumps, the authors propose PR-GRPO. This method utilizes Routing Shifts to suppress instability, significantly improving the stability of MoE reinforcement learning. As shown in Figure 5, the authors display the Empirical Cumulative Distribution Function (ECDF) of Router-shift. The results show that PR-GRPO shifts the distribution to the left with a lighter tail, consistent with the mean stability mentioned in the text, indicating that this method effectively reduces extreme routing changes and enhances training stability.
- Reward-Augmented Load Balancing: Traditional load balancing focuses only on activation frequency, which can easily lead to expert homogenization. The load balancing mechanism proposed by PADD jointly models expert activation frequency and performance quality. By increasing the activation probability of high-quality experts, this method mitigates the “expert homogenization” phenomenon induced by traditional load balancing and enhances long-term division of labor and collaboration among MoE experts.
Experimental Results and Analysis
The authors conducted experiments on mathematical reasoning benchmarks to evaluate the effectiveness of the PADD framework. The experimental results indicate:
- Performance Gain: Under the same inference cost, PADD achieved substantial performance improvements compared to strong baseline methods.
- Surpassing the Teacher: The MoE student model can match or even exceed the performance of its dense teacher model, proving the effectiveness of distillation from dense to MoE.
- Routing Stability: The experiments demonstrated effective teacher-to-student knowledge distillation and stable routing behavior, validating the roles of PR-GRPO and load balancing mechanisms.
Summary
The PADD framework proposed in this paper provides a unified solution for knowledge distillation from dense models to MoE models. Through a systematic design of four stages, PADD addresses core challenges such as router cold start, capacity gap, path rupture, and expert homogenization.
The authors’ main contributions are:
- Proposed a four-stage distillation framework containing initialization and training stages.
- Utilized teacher neuron clustering to construct student expert initialization, mitigating the cold start problem from the source.
- Proposed online adaptive distillation and the PR-GRPO algorithm, improving the stability of MoE reinforcement learning.
- Designed reward-augmented load balancing to optimize expert division of labor.
This research provides new ideas for guiding MoE student learning using dense teacher models under a fixed computational budget, demonstrating the huge potential of the MoE architecture in inheriting knowledge from dense models.
This note was included in the arXiv daily digest 20260616. More roundups at blog archive .