Persona-Pruner: Sculpting Lightweight Models for Role-Playing
Authors: Jinsu Kim, Jihoon Tack, Noah Lee, Jongheon Jeong
The authors propose the Persona-Pruner framework, which isolates role-specific subnetworks from general large models through role-driven data synthesis and learning-based subnetwork discovery, enabling lightweight deployment.
Paper Summary
Problem
The paper addresses the high computational cost of large models in role-playing scenarios and the severe performance degradation caused by traditional pruning methods that fail to distinguish between redundant knowledge and role-specific traits.
Method Overview
- Backbone: Transformer-based LLM
- Key module: 角色驱动数据合成、FFN 层二值剪枝掩码学习
- Loss: 基于合成数据的生成损失优化
Takeaways
Personal understanding — corrections welcome
Experiments show that specific roles rely on only a small fraction of the model's total capacity; the method reduces performance degradation by 93.8% on RoleBench while preserving general capabilities.
Limitations & Questions
The approach relies on synthetic data quality; the generalization of pruning masks requires further validation; performance under extreme sparsity is not explicitly addressed.
Reading Notes
Personal reading notes. Original paper: arXiv:2606.14695v1.
arxiv_id: 2606.14695v1
arXiv Reading Note: Persona-Pruner: Sculpting Lightweight Models for Role-Playing
Research Background and Motivation
With the advent of the Large Language Model (LLM) era, role-playing chatbots have demonstrated significant potential in scenarios such as personal assistants, game NPCs, and simulating user-preferred personas. However, the paper points out that when applying these capabilities to real-world applications (e.g., ecosystems involving simultaneous interactions with numerous NPCs), critical efficiency issues are exposed, specifically excessive computational costs.
The authors question whether assigning a complete general-purpose model to a single persona is necessary and propose the hypothesis that specific persona identities may rely on only a small fraction of the model’s total capacity. Existing naive pruning methods often fail to distinguish between redundant knowledge and essential persona characteristics, leading to a severe decline in role-playing performance for specific personas. Therefore, how to maintain role-playing fidelity while reducing computational costs becomes the core problem addressed in this paper.
Core Method: Persona-Pruner Framework
To address the above issues, the authors propose the Persona-Pruner framework. This framework aims to sculpt a general foundation model into a specialized role-playing agent based solely on text-based persona definitions. Unlike traditional methods that require large amounts of real role-playing data, Persona-Pruner directly aligns the pruning process with the target persona to identify and retain relevant sub-networks.
The framework mainly consists of two core phases:
- Persona-driven Data Synthesis: By rewriting arbitrary general datasets based on persona definitions, calibration data is generated. This process eliminates the reliance on pre-existing role-playing corpora.
- Learning-based Persona Sub-network Discovery: Utilizing the synthesized specialized data, binary pruning masks for the intermediate dimensions of Feed-Forward Networks (FFN) within Transformer blocks are optimized, ensuring that only “persona-critical” weights are selectively retained.
The paper illustrates the overall overview of this framework via Figure 1. As shown in the figure, the process starts from General Instruction Data, generates Synthetic Persona Data through persona-sensitive query filtering and persona-conditional answer rewriting. Subsequently, these data are used for mask learning on the FFN layers, ultimately yielding the pruned model.
Experimental Results and Performance Evaluation
The authors conducted extensive evaluations of the proposed framework, comparing it with competitive pruning baselines. Experimental results indicate that Persona-Pruner can effectively identify and retain persona-critical sub-networks, achieving superior role-playing fidelity compared to baselines even without additional training.
In the RoleBench benchmark, evaluated using LLM-as-a-judge scoring, Persona-Pruner reduced the performance degradation of dense models by up to 93.8% (compared to the strongest baseline). Furthermore, even at high sparsity levels (e.g., 50%), the pruned model maintains high-fidelity performance after brief recovery fine-tuning.
Figure 3 shows the analysis results based on LLM-as-a-judge scores. The chart compares the performance of different methods at various sparsity levels, intuitively reflecting the advantage of Persona-Pruner in maintaining role-playing capabilities.
Notably, evaluations on standard benchmarks confirm that this targeted pruning does not compromise the model’s general reasoning capabilities. The pruned model maintains performance comparable to other baselines, proving that the method successfully retains general knowledge while prioritizing persona characteristics.
Mask Analysis and Insights
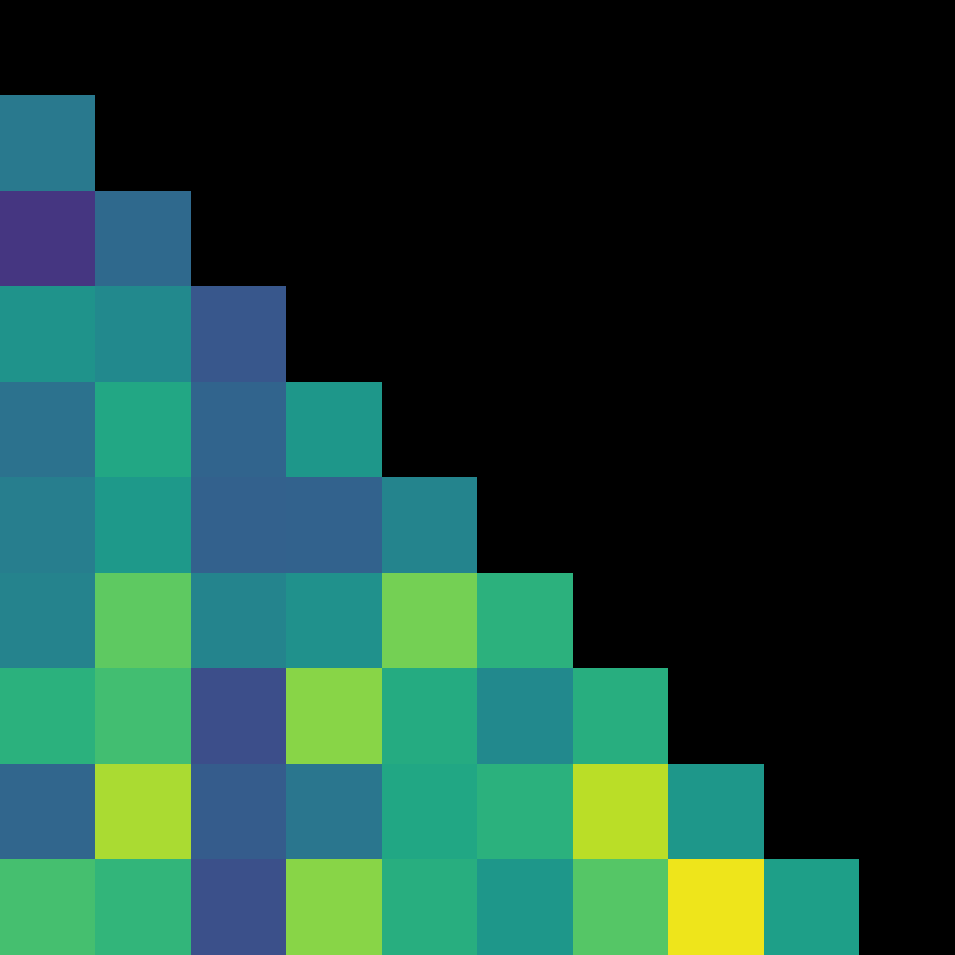
To deeply understand the pruning mechanism, the paper conducts correlation analysis and similarity analysis on persona-specific pruning masks.
Figure 4 shows the correlation analysis of persona-specific pruning masks. By observing the correlation between masks of different personas, the authors attempt to reveal whether different personas occupy different subspaces in the model parameter space.
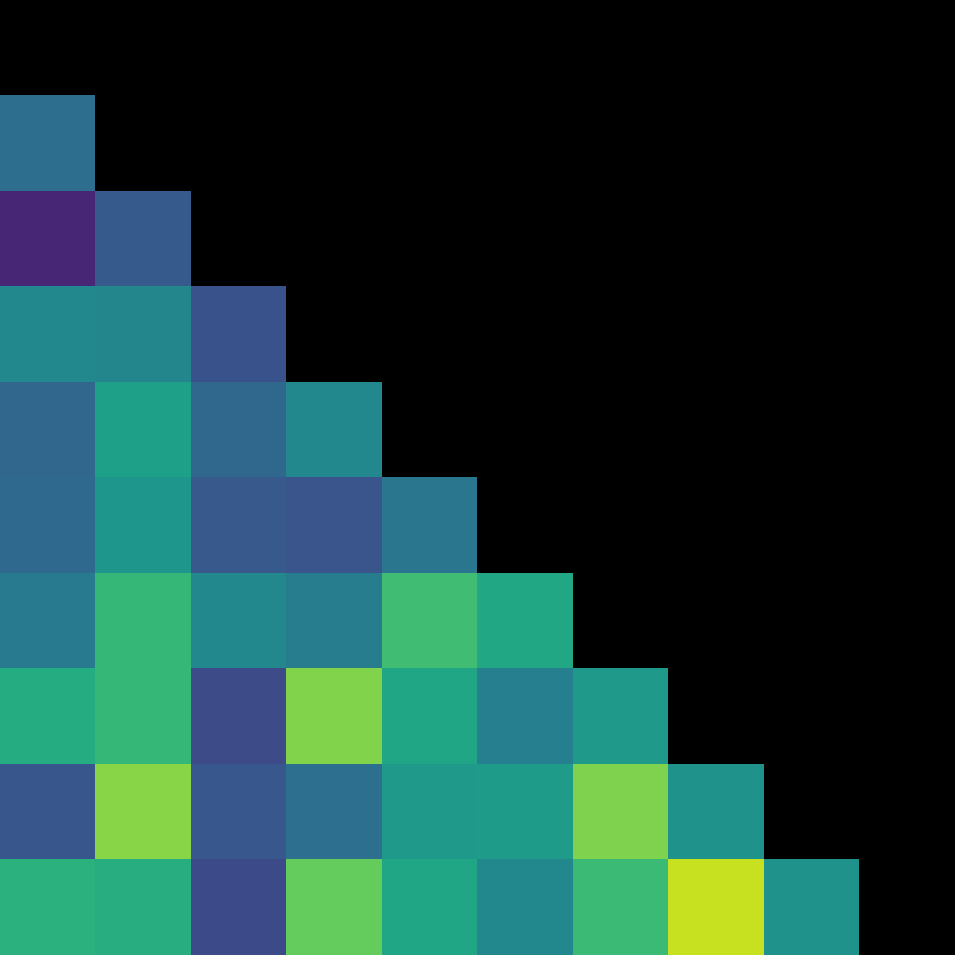
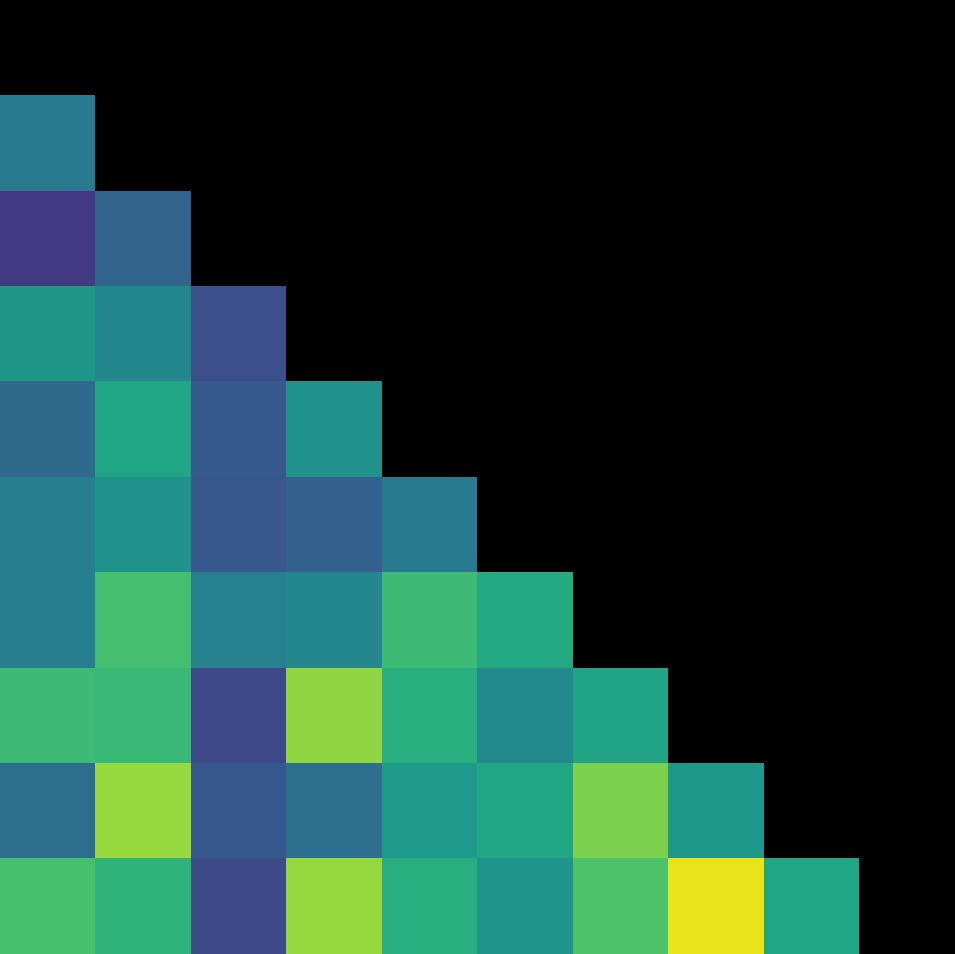
Additionally, Figure 5 provides a heatmap of pairwise Jaccard similarity for persona-specific masks. This figure further quantifies the differences in pruning patterns between different personas, verifying that different personas indeed rely on different subsets of parameters within the model, thereby supporting the hypothesis that “specific persona identities rely on only a small fraction of the model’s capacity.”
Summary
Persona-Pruner proposes a novel model pruning framework specifically designed for building lightweight role-playing models. Through persona-driven data synthesis and learning-based sub-network discovery, this method successfully minimizes role-playing performance loss while reducing computational costs. Experiments demonstrate that the method significantly outperforms existing state-of-the-art LLM pruning techniques on RoleBench without sacrificing the model’s general capabilities. This work provides a feasible solution for deploying large-scale role-playing systems in resource-constrained environments.
This note was included in the arXiv daily digest 20260616. More roundups at blog archive .