IEA: Amateur-Friendly Conversational Image Editing Agent via Three Stages of Multitask Alignment
Authors: Zichen Zhu, Yuheng Sun, Mingxuan Zhu, Wenjie Ma, Situo Zhang
The authors propose IEA, a conversational image editing agent that performs editing by manipulating parameterized tools within an explicit action space. It employs a three-stage multitask alignment training process: expert editing distilled SFT, GRPO-based reinforcement learning, and large-scale synthetic fine-tuning, to achieve interpretable editing trajectories and user intent summarization.
Paper Summary
Problem
Existing image editing software is polarized; professional software has a steep learning curve, while mobile filters lack fine-grained control. Generative models often produce artifacts and lack interpretability, making it difficult to bridge the gap between amateur user intent and final results.
Method Overview
- Backbone: VLM (Visual Language Model)
- Key module: 三阶段训练管道 (SFT, GRPO, 合成微调), 16 种参数化工具调用,意图总结模块
- Loss: GRPO 奖励函数 (相似度改进、工具有用性、意图总结)
Takeaways
Personal understanding — corrections welcome
Experiments show that a tool-centric VLM combined with an interpretable action space effectively improves instruction-following capabilities and perceptual quality. The three-stage alignment strategy significantly outperforms strong baselines, and the editing trajectories are transparent and debuggable.
Limitations & Questions
It relies on the coverage of parameterized tools and may not handle complex editing requirements beyond the defined scope of 16 tools. The quality of synthetic data may affect final generalization capabilities, requiring further verification.
Reading Notes
Personal reading notes. Original paper: arXiv:2606.08016v1.
arxiv_id: 2606.08016v1
IEA: An Amateur-Friendly Conversational Image Editing Agent Based on Three-Stage Multi-Task Alignment
1. Background and Motivation
With the popularity of digital photography, image editing has become a common activity for both amateur users and professionals. However, existing editing tools show a clear polarization: professional desktop software (such as Photoshop and Lightroom) is powerful but has a steep learning curve, deterring amateur users; while mobile-based “one-click filters” or automatic enhancement features are convenient, they lack fine-grained control capabilities and space for personalized expression.
The paper points out that while existing generative models can create images from scratch based on instructions or inpaint based on references, they are often computationally intensive. Moreover, the generated images may contain artifacts, unreasonable details, or style drift deviating from photographic realism, and they fail to provide logical insights behind the edits. Many agents based on Vision-Language Models (VLMs) have made progress in tool calling and GUI control, but external editors introduce time-consuming communication, and reward signals are often linked only to overall visual effects, which may lead to redundant or suboptimal tool usage.
To bridge this gap, the authors propose IEA (Image Editing Agent), a conversational image editing agent that interacts with users via natural language commands. IEA can automatically generate specific and interpretable tool calls to achieve lossless, high-fidelity photo editing while preserving the authenticity of the editing results.
2. IEA Core Framework
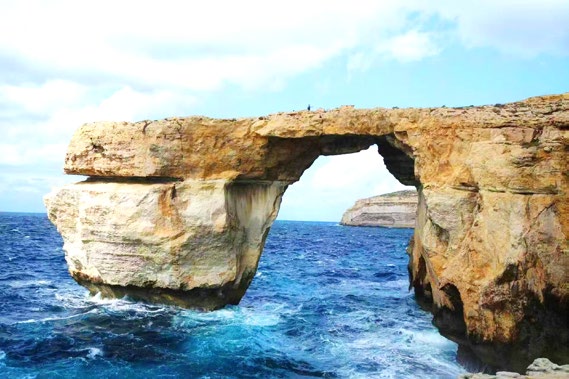
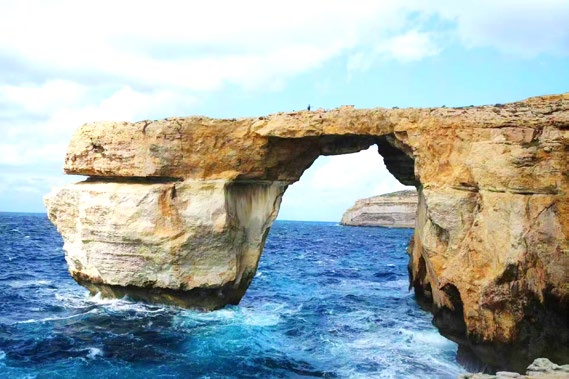
The core of IEA lies in enabling VLMs to learn to operate parameterized tools within an explicit, interpretable action space. Users only need to input natural language instructions (e.g., “make the rocks look brighter”), and the agent can analyze the image content, generate corresponding tool call parameters, and output a transparent editing trajectory for user inspection and debugging.
As shown in Figure 1, users can not only interact with IEA to edit images according to their preferred styles but also simply enhance them based on general professional knowledge. IEA can also learn user intent based on previous attempts. For example, when a user requests “enhance the image,” the agent analyzes shadow areas and increases brightness; when a user requests “enhance based on professional knowledge,” the agent performs multi-round adjustments, including specific parameter changes for temperature, contrast, saturation, and brightness.
3. Three-Stage Training Process
The training framework of IEA includes three core stages aimed at optimizing strategies through multi-task alignment. The overall framework is shown in Figure 2, covering the data pipeline and the training process of the three stages.
3.1 Stage 1: Supervised Fine-Tuning (SFT)
This stage constructs a high-quality dataset by distilling expert edits. The authors utilize powerful VLMs and lightweight heuristic parameter search to distill tool parameter plans from expert edits to better match expert results. This stage initializes tool usage and instruction summarization capabilities.
3.2 Stage 2: Reinforcement Learning (GRPO)
The paper adopts Group Relative Policy Optimization (GRPO) to optimize the agent’s policy. The reward signal not only captures improvement in distance to the reference edit but also captures the marginal utility of each tool call. Additionally, a small reward model is trained to guide the reverse image summarization task.
3.3 Stage 3: Large-Scale Synthetic Fine-Tuning
The final stage utilizes large-scale synthetic supervision to expand instruction coverage and critically achieves the Image-Refine capability, i.e., gradually improving previous attempts based on user feedback. This stage enhances reasoning capabilities, tool proficiency, and generalization ability.
4. Multi-Task Alignment Design
To comprehensively master image editing capabilities, IEA designs three main tasks, corresponding to different training objectives and data forms.
4.1 Image Editing Task (Image-Edit)
This task requires the model to analyze the image and user instructions to provide tool calls and reasoning logic. As shown in Figure 3, the model receives the original image and instructions (e.g., “significantly enhance brightness while slightly reducing saturation”) and outputs target tool parameters (e.g., brightness +50, saturation -15).
4.2 Image Summarization Task (Image-Summary)
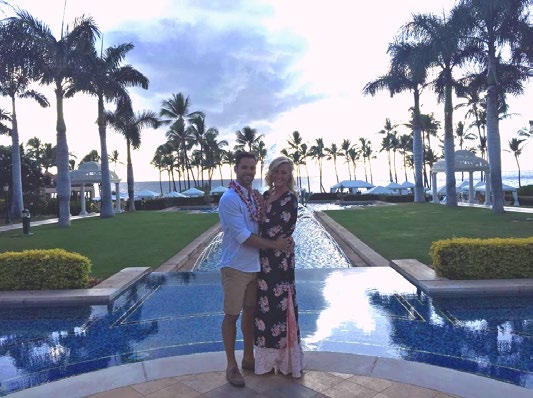
This is a reverse task aimed at summarizing user instructions based on editing results. As shown in Figure 4, the model infers the user’s original intent (e.g., “make the picture brighter, colors slightly softer”) based on the edited image and parameter changes. This helps the model understand the semantics behind editing operations.
4.3 Image Refinement Task (Image-Refine)
This task allows the model to make incremental improvements to previous editing attempts based on user feedback. As shown in Figure 6, when a user provides feedback such as “the image is not bright enough, slightly reduce contrast,” the model can adjust based on the previous editing trajectory to generate new parameter combinations.
4.4 Similarity Improvement Reward
In the reinforcement learning stage, the paper designs a reward mechanism to measure the similarity improvement between the editing result and the reference image. As shown in Figure 5, this mechanism checks mismatches by calculating differences and adjusts the reward value accordingly, guiding the model to generate editing parameters that better align with user perceptual goals.
5. Experimental Results and Analysis
The authors verified the effectiveness of IEA through quantitative experiments and user studies.
- Quantitative Experiments: On the expert test dataset, IEA achieved an average pixel distance of 0.1034 (lower is better) on the image editing task and a Rouge-L score of 0.2575 (higher is better) on the image summarization task, both outperforming strong baseline models.
- User Study: In terms of tool calling methods, IEA ranked highest in instruction following; in overall image quality assessment, IEA surpassed all baselines, including diffusion-based generative methods.
These results indicate that combining VLMs with symbolic, controllable tools is an effective path to achieving reliable, interpretable, and preference-aligned image editing.
6. Summary
IEA proposes an amateur-friendly conversational image editing agent that resolves the contradiction between usability and controllability in existing tools through three-stage multi-task alignment training. The main contributions of the paper include:
- Proposing IEA, a VLM-driven agent capable of analyzing images and instructions, selecting appropriate tool parameters, summarizing user intent, and refining results based on feedback.
- Constructing a high-quality dataset of approximately 29,000 samples (distilled from GIER) and a large-scale synthetic dataset of approximately 400,000 samples.
- Developing a three-stage training recipe including SFT, GRPO, and synthetic data fine-tuning.
- Demonstrating the superiority of IEA in instruction following and image quality through quantitative experiments and user studies.
This work validates that interpretable, tool-centric VLMs serve as a reliable path for human instruction-guided image retouching, providing new ideas for the design of future image editing tools.
This note was included in the arXiv daily digest 20260616. More roundups at blog archive .